A support bot gives customers last year’s refund policy. A sales copilot invents a feature that was retired two quarters ago. A content assistant knows the product catalog but writes like a cheerful intern when your brand needs a sharp operator. The RAG vs fine-tuning decision sits behind all three failures, and it should be made before a team spends months polishing prompts.
The short version is simple: use retrieval-augmented generation, or RAG, when the model needs access to current, auditable information. Use fine-tuning when it needs to consistently perform a specialized behavior, follow a difficult format, or communicate in a particular style. Most serious AI systems eventually use both, but not as a shortcut around weak data, vague workflows, or missing evaluation.
RAG vs fine-tuning is a systems decision
RAG gives a language model a search layer. Before answering, the system retrieves relevant material from a controlled knowledge base, then supplies that material as context for the model’s response. Think policy documents, product specifications, operating procedures, account notes, contracts, inventory feeds, or an internal wiki.
Fine-tuning changes the model’s behavior through additional training examples. Instead of handing it a current policy at query time, you teach it patterns: how to classify an incoming request, produce a structured output, write in a house style, translate a messy customer brief into a job ticket, or recognize when a workflow must be escalated.
Those are different jobs. Confusing them creates a familiar mess: teams fine-tune a model on documents that will change next month, then discover that updating knowledge requires another training cycle. Or they build RAG for every problem, then wonder why the model cannot reliably follow a strict JSON schema or make consistent judgment calls from sparse instructions.
The useful question is not, “Which technique is better?” It is, “What must be current, what must be repeatable, and what can be verified?”
Choose RAG when the facts move
RAG is the stronger default for knowledge-intensive business work because company information does not sit still. Prices change. Policies are revised. Product releases create new edge cases. A travel planning assistant needs current availability and local constraints, not a memory of a guidebook from six months ago.
It also provides a better path to traceability. A well-built RAG system can show the source passages used for an answer, record retrieval results, and let an operator diagnose whether the failure came from missing content, bad search ranking, or weak model reasoning. That matters in customer service, operations, legal-adjacent work, and any workflow where a confident wrong answer has a real cost.
RAG is not merely uploading PDFs to a chatbot. The quality of the corpus determines the quality of the system. A folder full of duplicate decks, outdated SOPs, image-only scans, and conflicting policy language will produce unreliable answers no matter which model sits on top.
A practical RAG implementation starts with content ownership. Each document needs an accountable owner, a revision date, a clear status, and a reason to exist. Content should be broken into meaningful sections rather than arbitrary character counts. Metadata should identify the department, product, geography, effective date, audience, and permission level. Those fields often matter as much as semantic search.
Consider a multi-location restaurant group. The assistant should retrieve the current prep standards for the correct location, account for local health rules, and distinguish a corporate recipe from a temporary limited-time menu. If retrieval ignores location and date, the system can sound precise while sending the wrong procedure to the line.
RAG has limits. Retrieval can miss the best source, pull in contradictory passages, or overload the model with too much context. It also cannot compensate for a document that never captured how experienced staff actually make decisions. Search is not judgment.
Choose fine-tuning when behavior is the product
Fine-tuning earns its keep when the same behavioral requirement appears repeatedly and prompt engineering has become a brittle pile of exceptions. The strongest use cases tend to be narrow, high-volume, and easy to evaluate.
A company may need to classify support tickets into a fixed taxonomy, extract fields from invoices, generate compliant call notes, or produce standardized work orders from technician transcripts. In each case, the goal is not to teach the model a changing body of facts. The goal is to make its output more consistent, faster, and cheaper to produce at scale.
Brand voice can be a valid fine-tuning use case, but teams often reach for it too early. A clear system prompt, a compact style guide, and a handful of examples can handle many editorial tasks. Fine-tuning becomes compelling when the desired voice includes recurring judgment patterns that are hard to state cleanly: what to cut, what to challenge, how to prioritize evidence, and where a writer should refuse empty claims.
Training data is the real cost center. A few hundred weak examples do not create expertise. They can harden bad habits, encode inconsistent labels, or teach the model to imitate superficial phrasing without learning the underlying decision. Every example should represent the output you would approve in production.
This is why fine-tuning needs a holdout set. Keep a separate group of representative examples out of training, then test the tuned model against the baseline model under the same conditions. Measure the things that matter to the workflow: exact format compliance, routing accuracy, edit time, escalation quality, or error rate. “It feels better” is not an operating metric.
The decision matrix teams actually need
| If your core need is… | Start with… | Why | |—|—|—| | Current policies, catalogs, research, or internal documents | RAG | Knowledge can be updated without retraining the model. | | Consistent classification, extraction, or structured output | Fine-tuning | Repeated examples can improve behavior and reduce prompt complexity. | | Answers that require citations or source review | RAG | The system can retrieve and expose the supporting material. | | A specialized workflow using current company data | Both | Fine-tuning handles the task pattern; RAG supplies current facts. |
The fourth row is where mature implementations land. A field-service assistant, for example, might be fine-tuned to turn technician notes into a standardized service report. It would use RAG to pull the current equipment manual, warranty terms, and location-specific service history. One layer shapes execution. The other supplies evidence.
Build the evaluation before the interface
The expensive mistake is building a polished chat interface before defining a test set. AI systems should be evaluated like operational systems, not treated like a clever demo.
Start with 30 to 100 real requests that represent normal volume, ugly edge cases, ambiguous questions, and high-risk scenarios. Include requests the system should decline or escalate. For each one, define what a good answer needs: correct source selection, a specific action, a valid schema, a human-review flag, or simply a concise response that does not overclaim.
Then test the baseline model, the RAG version, and any fine-tuned version against the same set. Review failures by category. If RAG answers are wrong because the right material was never retrieved, do not solve it with more prompting. If a fine-tuned model has the right facts but produces inconsistent outputs, inspect your training examples and output constraints. The fix should match the failure.
Security belongs in this design stage as well. Retrieval systems need document-level permissions, not a single shared pile of company knowledge. Fine-tuning data needs careful review for customer information, confidential material, and training rights. A system that leaks a private compensation policy is not made safer because it produces elegant prose.
Avoid the false choice
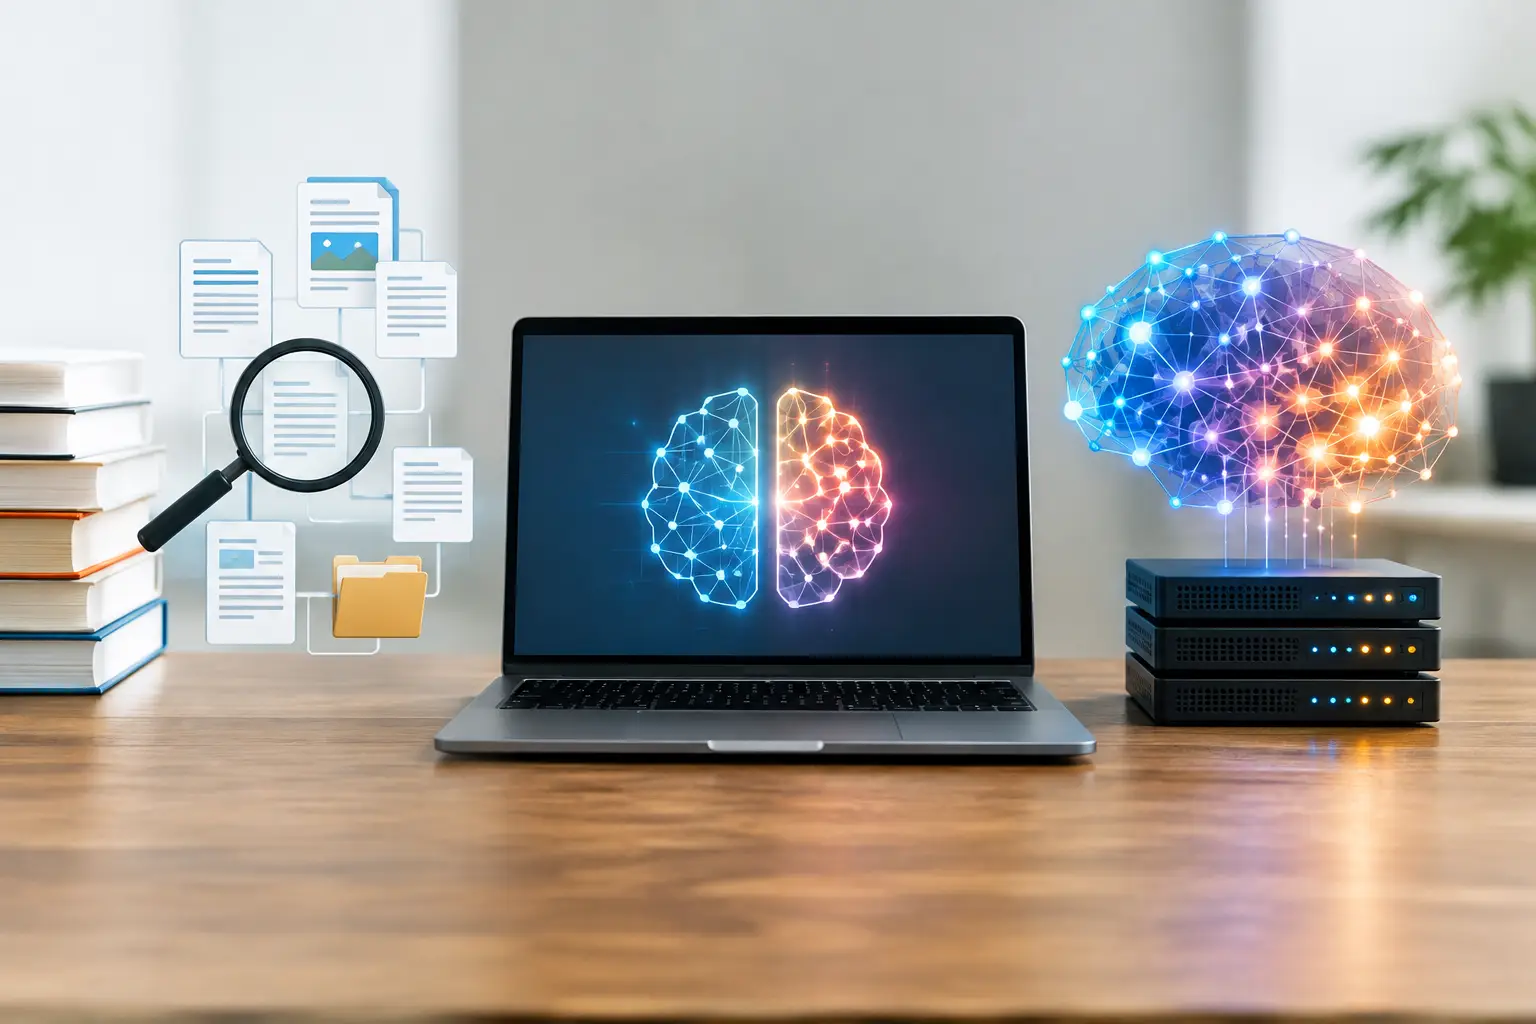
RAG and fine-tuning are often presented as competing paths because that makes for an easy slide. In practice, they solve separate parts of the architecture. RAG is your knowledge supply chain. Fine-tuning is your process standardization layer.
For many teams, the sensible order is RAG first. It forces the organization to confront whether its knowledge is current, organized, permissioned, and usable. Then fine-tune only after a repeated task has enough volume, enough stable examples, and enough measurable value to justify the effort.
The best AI system is rarely the one with the most elaborate model strategy. It is the one that knows when to retrieve a current answer, when to apply a learned pattern, and when to hand the decision back to a person who owns the consequences.